Disconnected by Design: The Real Price of Siloed Engineering Data—and What Integration Actually Delivers
There is a particular kind of organizational dysfunction that rarely appears on a balance sheet, yet steadily undermines operational performance across US industrial facilities. It does not announce itself through a single catastrophic failure. It accumulates quietly—in the hours technicians spend reconstructing work histories that already exist somewhere else in the organization, in the maintenance decisions made without access to engineering specifications, in the safety audits that miss patterns visible only when disparate datasets are viewed together.
Data silos in manufacturing and industrial operations are not a new problem. But as facilities grow more instrumented, more automated, and more dependent on real-time decision-making, the cost of fragmented information systems is rising faster than most organizations recognize.
How Silos Form—and Why They Persist
Understanding why data silos exist is a prerequisite to dismantling them. In most industrial organizations, siloed systems are not the product of negligence. They are the accumulated result of rational decisions made at different points in time by different functional groups.
Engineering teams select CAD and product lifecycle management platforms optimized for design workflows. Operations departments implement ERP and SCADA systems built around production scheduling and real-time monitoring. Maintenance organizations adopt CMMS platforms focused on work orders, asset histories, and parts inventories. Each selection is defensible in isolation. The problem emerges at the boundaries.
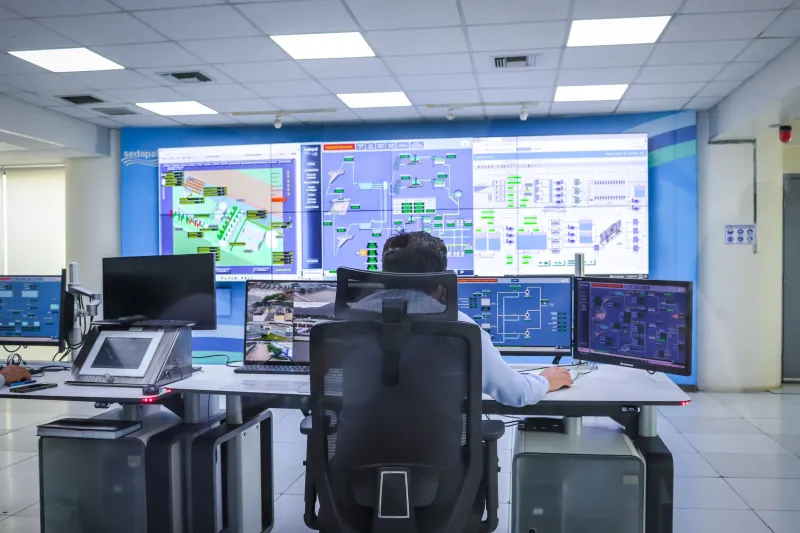
When these platforms do not share a common data architecture—or when integration is deprioritized during implementation—information generated in one system rarely flows usefully into another. A design change documented in the engineering environment may not reach the technicians responsible for maintaining that equipment. Failure data captured in the CMMS may never inform the next design iteration. Operational anomalies flagged by SCADA may sit unanalyzed because no one has established a pathway between the monitoring system and the engineering team positioned to diagnose root causes.
The silos persist because addressing them requires cross-functional coordination, budget alignment, and a willingness to challenge the organizational structures that have grown up around the separated systems. None of those are easy asks.
Measuring the Actual Cost
The financial impact of data fragmentation is rarely captured in a single line item. It surfaces across multiple operational dimensions simultaneously, which is part of why it tends to be underestimated.
Redundant work is the most visible symptom. When engineering documentation is not accessible to maintenance teams, technicians often rebuild technical context from scratch—or work from outdated information that no longer reflects the current state of the asset. Studies of mid-sized US manufacturing operations have found that maintenance personnel can spend between 15 and 30 percent of their time searching for information rather than applying it. At scale, that represents a significant and largely avoidable labor cost.
Delayed troubleshooting compounds the problem. When a production line goes down, every minute of unplanned downtime carries a measurable cost. In automotive and food processing environments, that figure can exceed several thousand dollars per hour. The ability to rapidly correlate operational anomalies with engineering specifications, maintenance histories, and environmental conditions is the difference between a two-hour resolution and a twelve-hour investigation. Facilities that lack integrated data infrastructure consistently land closer to the latter.
Missed safety signals represent perhaps the most serious consequence. Safety incidents rarely emerge from a single failure. They develop from the convergence of multiple contributing factors—equipment degradation, procedural gaps, environmental conditions—that individually fall below alarm thresholds but collectively create risk. When the data necessary to identify these convergences lives in separate, non-communicating systems, the signal never forms. Organizations that have consolidated their data environments consistently report an improved ability to identify precursor conditions before they escalate.
Suboptimal asset lifecycle decisions round out the picture. Capital-intensive industrial equipment represents a substantial portion of the asset base for most US manufacturers. Decisions about when to repair, refurbish, or replace that equipment should draw on engineering performance data, operational utilization history, maintenance cost trends, and failure pattern analysis. When those data streams are fragmented, lifecycle decisions default to rules of thumb and calendar-based schedules rather than evidence-based analysis—frequently resulting in either premature replacement or deferred action that allows degradation to progress into failure.
What Integration Looks Like in Practice
The term "data integration" can obscure more than it clarifies. In industrial contexts, it does not necessarily mean replacing every existing platform with a single monolithic system. For most organizations, the more practical path involves establishing interoperability between existing systems through common data standards, API-driven integration layers, or purpose-built industrial data platforms that aggregate information without requiring full platform consolidation.
A Midwest-based precision components manufacturer undertook this type of integration initiative after identifying that their engineering and maintenance teams were operating from asset records that had diverged significantly over time. The integration project—which connected their PLM environment to their CMMS through a standardized data layer—reduced average troubleshooting time by approximately 35 percent in the first year and enabled the maintenance team to shift a meaningful portion of their work order volume from reactive to condition-based scheduling.
A Gulf Coast petrochemical facility pursued a similar initiative focused specifically on safety data. By establishing a unified view that correlated process monitoring data with inspection records and near-miss reports, the facility's safety team identified a recurring equipment condition that had been invisible within any single data system. Addressing that condition before it escalated represented not only a safety improvement but a significant avoided-cost outcome.
Building the Business Case
For engineering and operations leaders making the case for data integration investment, the ROI argument is most effective when it quantifies impact across multiple dimensions simultaneously. Downtime reduction, labor efficiency gains, maintenance cost avoidance, and risk mitigation each contribute to the overall return—and the combination typically produces a compelling picture even when individual line items appear modest.
Equally important is framing integration as infrastructure investment rather than IT expenditure. The ability to make faster, better-informed decisions about assets, processes, and safety conditions is a competitive capability, not a back-office function. Organizations that treat their data architecture as a strategic asset are better positioned to respond to operational disruptions, regulatory changes, and market shifts than those that treat it as a maintenance burden.
The manufacturing organizations that are pulling ahead in operational efficiency are not necessarily those with the most advanced individual systems. They are the ones that have made those systems talk to each other—and built the organizational practices to act on what the integrated view reveals.
For facilities still operating in a fragmented information environment, the question is no longer whether integration is worth pursuing. It is how much longer the status quo can be sustained before the accumulated cost of disconnection becomes impossible to ignore.